How Do You Judge an AI?
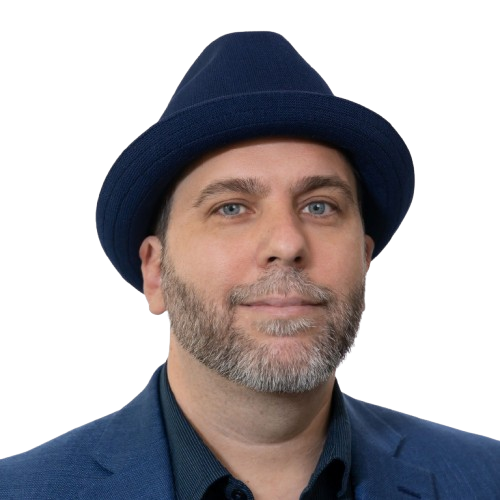
I lived in The Great State of Texas for more than 25 years (interRel was headquartered there from the day we filed the paperwork at the Dallas courthouse until the day I left), and the State Fair of Texas opened on Friday and runs through October 18, so I’ve decided that gives me the standing to turn my website into a county fair judging this week. My books are entered as preserves, my podcast is up for Best in Show, my MCP servers are out in the barn with the tractors under mechanical exhibits (they fit in better than I’d like), and there’s a life-size butter sculpture of me, in a butter fedora, that placed fourth out of 4 entries. (Edward, you had an AI generate a picture of you losing a butter sculpture contest to 3 people who don’t exist, then you wrote the judge’s comments yourself, and you still only gave yourself a 1 out of 10 for humility, which is the one score on the page nobody is going to dispute.)
I also dressed up as Big Tex (well, an AI dressed me up as Big Tex, which is how I get into most costumes these days), and it got everything right except the hat, which is a giant blue fedora, on purpose, for reasons my family understands and nobody else needs to.
I’ve been scored against a published rubric for most of my career, and I’ve always liked it better than the alternative. The Essbase certification exam was a rubric (I got the first perfect score on it, a sentence I’ll apparently be working into conversations until I die). Most of the conference sessions I’ve given were scored by the audience afterward, which is where my 8 speaker awards came from, and also where a much larger pile of evaluations came from that I have chosen not to frame. Dawn and I vote on the TERPECA escape room awards every year (Top Escape Rooms Project Enthusiasts’ Choice Awards, which is a mouthful, so nobody says it), which means we play rooms all over the world with a scoring sheet running in our heads, and either of us can tell you exactly why any room on our list sits where it does (we’ll disagree, but we’ll both have reasons). None of that made me any better at jam… but it did make me very comfortable being told precisely where I lost the points.
The part of fair judging I actually love is that before a single jar of jam comes through the door, the fair publishes the rubric: the category, the criteria, and how many points each one is worth. Then a judge (usually somebody who has been doing this longer than you’ve been alive, and who has opinions about pectin that she’ll share whether or not you asked) scores every entry against it and writes down why, on a card, and the card gets taped next to your jar where you and your neighbors and your neighbors’ kids can all read it. You might hate the result, but you’ll know exactly where the points went, and if you placed third you’ll know it was the shelf life and not the clarity, and what to fix before next year.
Now compare that to how a lot of companies judge an AI pilot, which in my experience goes something like this: somebody picks a use case in the spring, a vendor runs it for a quarter (sometimes 2), and in the fall there’s a slide with a green checkmark and the word “success” on it. What was it supposed to do, better than what, and measured how and by whom? I’ve asked some version of that in a lot of conference rooms over the last few years (dozens, easily, and I was asking it about Essbase cubes long before anybody called it AI), and the most common answer is a sort of wounded silence, as if I’d walked up to the jam and asked it what it was trying to accomplish.
Plenty of those pilots probably worked fine (most of them, I’d guess)! Nobody wrote the rubric before the entry came in, though, so there’s no way to know, and when there’s no way to know, the pilot gets judged on whoever presented it best, which is how you end up with a dozen AI projects in production and no idea which 2 of them are paying for the other 10.
So here’s the card I’d put on any AI pilot, and it’s the same card that’s on the home page this week so you can score your own. It has 4 criteria, 10 points each, and you’re supposed to fill it out before the pilot starts, which is the part everybody skips:
- What was it supposed to do, in 1 sentence? Written down, and dated, before anybody touched a model. If you had to reconstruct it afterward from the kickoff deck, that’s 5 points, and if the honest answer is “it was a pilot,” that’s zero.
- What number did it have to beat? If nobody measured how long the process took, or how often it was wrong, before the AI showed up, then you can’t say it’s faster or better now. You can only say it feels that way. (This is the same argument I’ve been having with finance systems since 1997, by the way, back when the number that didn’t match lived in somebody’s personal spreadsheet, usually one without Freeze Panes, which is its own crime, and I’d like to report that the argument has gotten easier, and I can’t.)
- What does it do when it doesn’t know? Every vendor demo shows you the model being right. Ask to watch it be unsure. If the vendor can’t make that happen in the demo, ask them why, and write down what they say.
- Whose name is on the output? A person, who checks it. If the answer is “the team,” it’s nobody, and if the answer is the vendor, I’d like to talk to you before your renewal.
My MCP servers placed third in mechanical exhibits on the home page, by the way, and I’d defend the score. They got a 10 on “does what the card says” and a 10 on “returns the real number” (you ask Essbase for last quarter’s number and you get last quarter’s number, not a plausible guess, which is the entire reason I built them), and then they lost almost everything on showmanship, because they’re plumbing, and plumbing doesn’t demo well next to a quilt (Chewbacca did half the flying at Yavin and didn’t get a medal, so they’re in good company).
I’ll make a prediction, and you can hold me to it.
By the end of 2027, the CFOs I talk to won’t fund an AI pilot without a written scorecard attached, the same way nobody gets a capital project approved without an ROI model. Check back with me in January 2028.
If you score your pilot on the home page and don’t love the placing, write me (Edward@Roske.AI) and tell me which criterion got you, because I’d genuinely like to know which one trips people most. Or come to the Caribbean AI Summit in San Juan on October 9 and 10 and bring your card. I’ll be the one in the blue fedora, and the lemonade’s on me.
Asking good questions, Edward