If You Can Read Every Line of an AI's Code, Do You Understand It?
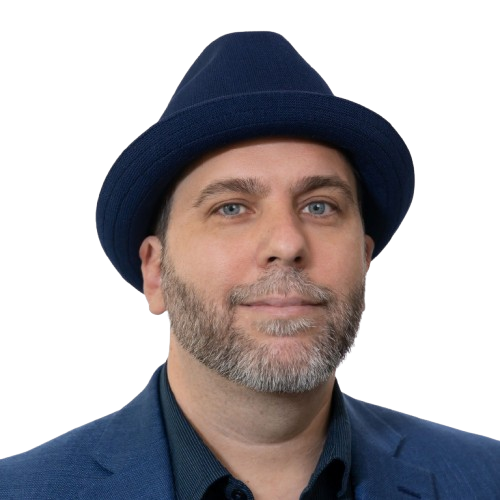
My website is a documentary about itself this week, and I’m the subject, which (to be fair to the machine that built it) I approved in advance, and which I’d like to blame on a movie.
The new Elizabeth Holmes documentary, You Can See Everything, has been in theaters since October 16, and it did about $15 million on its opening weekend in 855 theaters, which is the second-biggest opening a documentary has ever had, behind only Fahrenheit 9/11 back in 2004 (it still finished second that weekend to Street Fighter, and since my website was a Street Fighter arcade game last week, I’m choosing to take that personally, on behalf of the site). Nathan Fielder and Lance Oppenheim directed it, and the thing the title is poking at is that Theranos was a box nobody was allowed to open. When a federal court finally did, Holmes was convicted of defrauding investors and started her prison sentence in 2023. That’s all the Elizabeth Holmes you’re getting from me (there are roughly 400 other places on the internet to argue about her, and I’d rather talk about my website, which, if you know me, is not a surprise).
Which got me thinking about my own website, since it’s about as open as a box gets.
An AI agent rebuilds roske.ai from scratch every Saturday at 5AM. It picks the theme, writes the code, generates every picture of me (there’s a standing rule that I’m wearing a blue fedora in all of them, which it has, as far as I can tell, never broken, which is more than I can say for myself), runs the build and the tests, and pushes the whole thing live before I’m awake. The source code is public at github.com/ERoske/roske-ai-website, so you can see everything, literally. As of this morning, before this week’s commit, the repository had 244 commits going back to February 18, and 29 of those replaced the entire home page, and last week’s version alone touched 11 files, added 912 lines, and deleted 1,415 of them. (Edward, you have a Master’s in Data Science from SMU and you’re reading out line counts from your own hobby website like it’s an earnings call, and nobody asked, and you know nobody asked, and you’re going to keep going anyway because you’ve never met a number you didn’t want to say out loud…)
So I tried reading it (which I recommend to nobody), and it works, and I still can’t tell you why it made half the choices it made. Partly that’s because I haven’t read all of it (it’s a lot!), but mostly it’s because no person ever wrote the reasons down, so there’s nothing for me to find. Why is this week’s body text set in a typeface called Newsreader instead of the one it used 2 weeks ago? The agent will give you an answer if you ask (it’ll say something about newsprint), but that answer was generated by the same process that generated the choice, which is a bit like asking HAL to write up the incident report. I read the diff, and I couldn’t find the decision anywhere in it, and believe me, I scrolled.
Turns out Google has the same issue, at a scale slightly larger than my hobby website. In April, Sundar Pichai said 75% of all new code at Google is now AI-generated and approved by engineers, up from 50% the fall before. Satya Nadella put Microsoft’s number at 20 to 30% of the code in its repositories back in April of 2025, and I can’t find an update since. “Approved by engineers” is doing a lot of work in that Google sentence, by the way, and I believe it, though I’d love to be in the room when someone explains a Tuesday’s worth of it to the person whose job depends on it (ask anyone who’s ever signed a 300-page contract because the lawyers had read it).
The study I think about most on this came out of a research group called METR in July of 2025 (The Register wrote it up well). They took 16 experienced open-source developers, gave them 246 real tasks on code they knew intimately, and randomly let them use AI tools on some tasks and not others. The developers predicted the AI would make them 24% faster, it actually made them 19% slower, and afterward (having just lived through being slower) they still believed it had made them about 20% faster, which is a gap of roughly 40 percentage points between what they could see and what they understood about their own work.
Now, in fairness, my site’s record isn’t a disaster, and I want to be fair to the machine since it can’t speak for itself (well, it can, it did, there’s a whole statement from it on the home page this week, but you get my point). The honest list of failures, all of it sitting in the public commit history: on June 13 it built the whole redesign and forgot to commit it, so a backup script shipped it with the message “Claude completed the redesign but did not commit.” On August 1 it wrote “Ted Lasso comes back Wednesday” into the hero of a site that would still be up the following Saturday, and the fix landed on August 5, by hand. And on September 12 it built an entire escape-room theme, ran out of turns before committing, and the backup script that exists for exactly that situation died on a warning about Windows line endings, so roske.ai served a Labor Day theme until September 16 (11 days, which I know because I counted, twice). The clock on the machine doing all this has also recorded itself in 4 different time zones since July, which either means the laptop travels more than I do or it’s confused, and I travel a lot. So that’s 3 real incidents in 8 months (4 if you count the time zones, and I’m choosing not to), nobody’s data was involved, and if a contractor had that record I’d hire them again, probably without being able to explain a single decision they made, which bugs me more than the Labor Day thing did.
We’ve gotten used to trusting what we can see (the code, the audit trail, the logs, the SOC 2 report, you name it), and all of that is still good and you should still demand it. But I think we’re about 2 years from most of the important systems in a company being fully visible and not understood by anyone in the building, and I’d put real money on the first big “but we could see everything” failure getting a documentary too. (I could be wrong on the timeline. If so, write me in October 2028 and I’ll admit it in a blog post, probably one with even more parentheticals than this one, if that’s possible.)
I genuinely don’t know what trust looks like when the systems that matter are completely visible and nobody can explain them, and asking is sort of my whole thing (the show is literally called Asking Good Questions, and I’ve been getting away with it since Shimer College), so I’m asking you: is it the track record, or is it the person willing to put their name on it, the way my name is on a few hundred commits I didn’t type?
If you’ve got a room full of people who’d rather hear this out loud, the speaking page is for that, and I’ll bring the fedora. Or just write me at Edward@Roske.AI and tell me which systems at your company you can see but can’t explain (I’ve got a list going, and so far it’s mostly mine). Or come down to San Juan and Dawn and I will show you around, and I’ll point out the laptop that’s been to 4 time zones without me.
Asking good questions, Edward